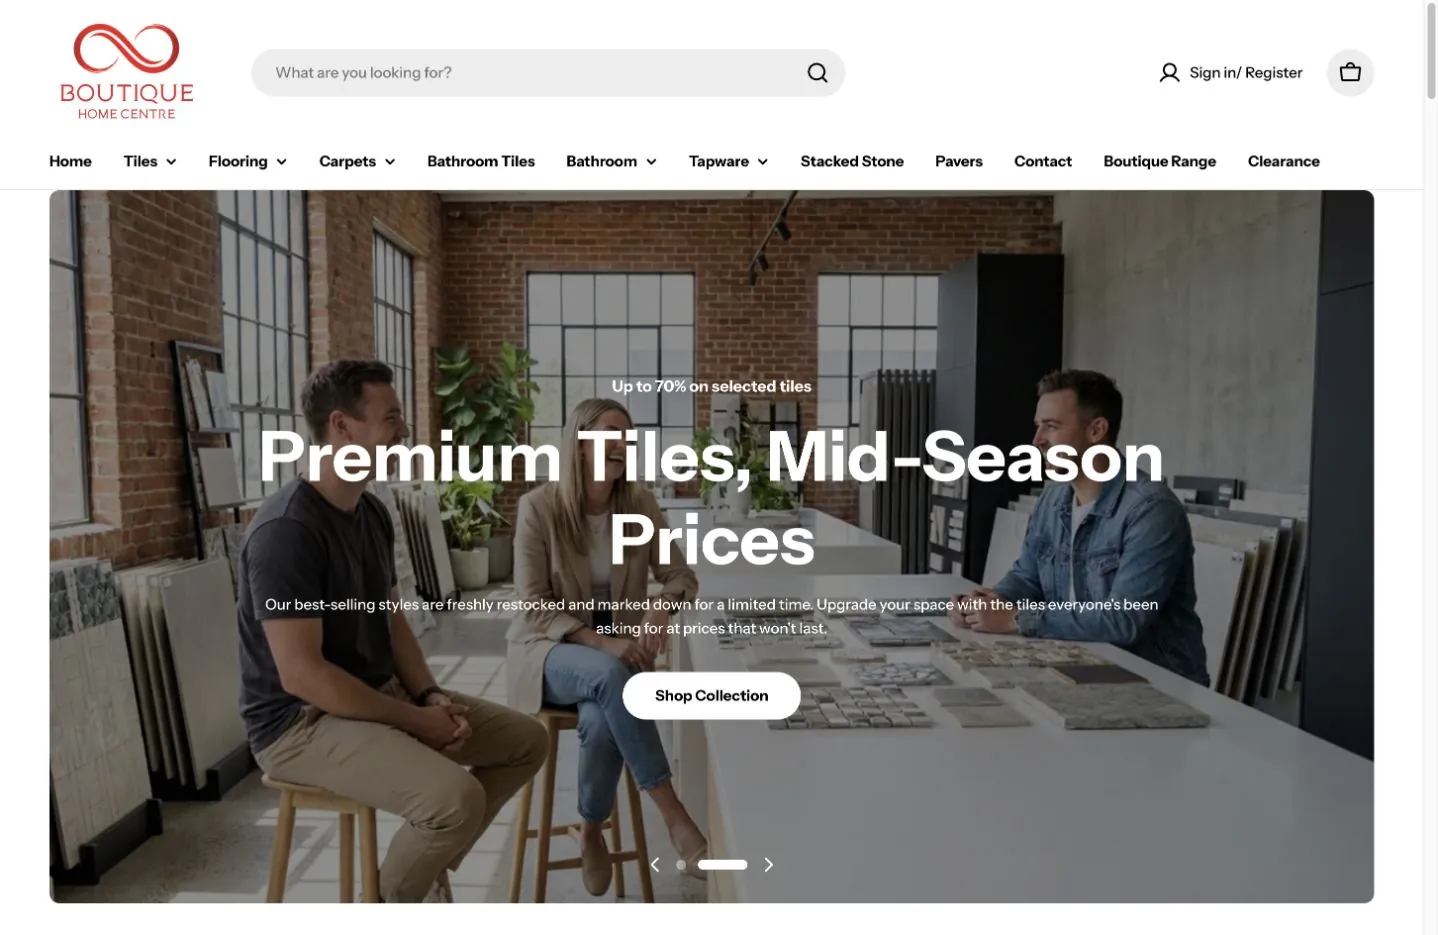
1/4 · A storefront organised around the renovation
Website development
Boutique Home Centre
Retail & productsWebsite designShopify
Melbourne, Australia
3,592
published product pages in the Shopify catalogue
Public sitemap review · 22 September 2026
Shopify website design for Boutique Home Centre in Melbourne, with a detailed product catalogue, AI-assisted content and a room visualiser.
Boutique Home Centre’s brief was to move its home-improvement catalogue into a better organised Shopify store and fill gaps in product information.
- Delivered: Product pages with useful descriptions, specifications and coverage details. Collections with filtering, sorting and product comparison.
- Outcome: Delivered a store where customers can find a product, compare its details, plan an order and ask about freight before buying.